

Agents write most of the code now, and it is becoming clear that code review hasn’t caught up with that. And code review is the least of it; the entire process around building software may need rethinking. The review loop most teams still run, where you open a pull request, collect comments, address them and ask for a re-review, was built for code that a person wrote and a person would fix.
Over the past few months I have changed how I review, mostly by trial and error. These are my notes on what works for me so far, and on the part of the process I think is broken.
One distinction before I start. I review code in two settings, and they have drifted apart.
On my non-critical projects, the review is mostly done before I see it. My agents build overnight, two or three models argue over the code, and I spend one to two hours in the morning reviewing what came back.
When I work with a team on something more critical and someone else opens a pull request, the old loop still runs in pretty much the same form: I find a problem, leave a comment, send it back to the author, wait for the fix, review again.
With an agent at hand, it starts to seem nonsensical. Writing the comment can cost roughly the same as patching the branch directly, and yet the fix still gets a round trip through someone else’s queue.
Here is what works for me.
Let the agents argue first
A different model reviews the change adversarially. The authoring agent addresses the findings, then the reviewer looks again. Nothing goes to a human, me included, until that loop is finished. On a team, that means no request for review before it. A human reviewer’s hour is the scarcest thing in the process.
I am surprised this isn’t an industry standard by now, or at least the default we start from.
Simplify between rounds
Left alone, agents bloat code. So I run a /simplify loop between reviews. But simplification changes the code too, so it belongs inside the review loop.
This part matters, because otherwise all those fixes and small additions quickly make the codebase grow. I’m beginning to suspect we should run automatic simplify loops over the whole codebase, daily or weekly, the way Dependabot keeps dependencies current, to keep tightening it. But that’s a topic for another time…
Multiple rounds
One review round finds most of it; two find a few more. I have had runs where the worst defect surfaced in the third or fourth. I have also seen reviewers start inventing objections after a few rounds. So you have to cap it somewhere.
Four is my current ceiling, and still an experiment. More rounds don’t automatically buy more confidence. Reviewing agents yap if you let them, and even when a later round finds a real mistake, it is often so small that fixing it (and complicating the codebase) isn’t worth it.
Give each reviewer one job
I don’t run a single reviewer. I run several specialised subagents, each with one job: one checks the security posture, another the architecture, a third the business logic, and so on. A narrow brief keeps each of them on its own question, and its findings are easier to judge.
Review the shape
By the time I look, two or three models have reviewed the lines, and the specialised reviewers have each covered their own angle.
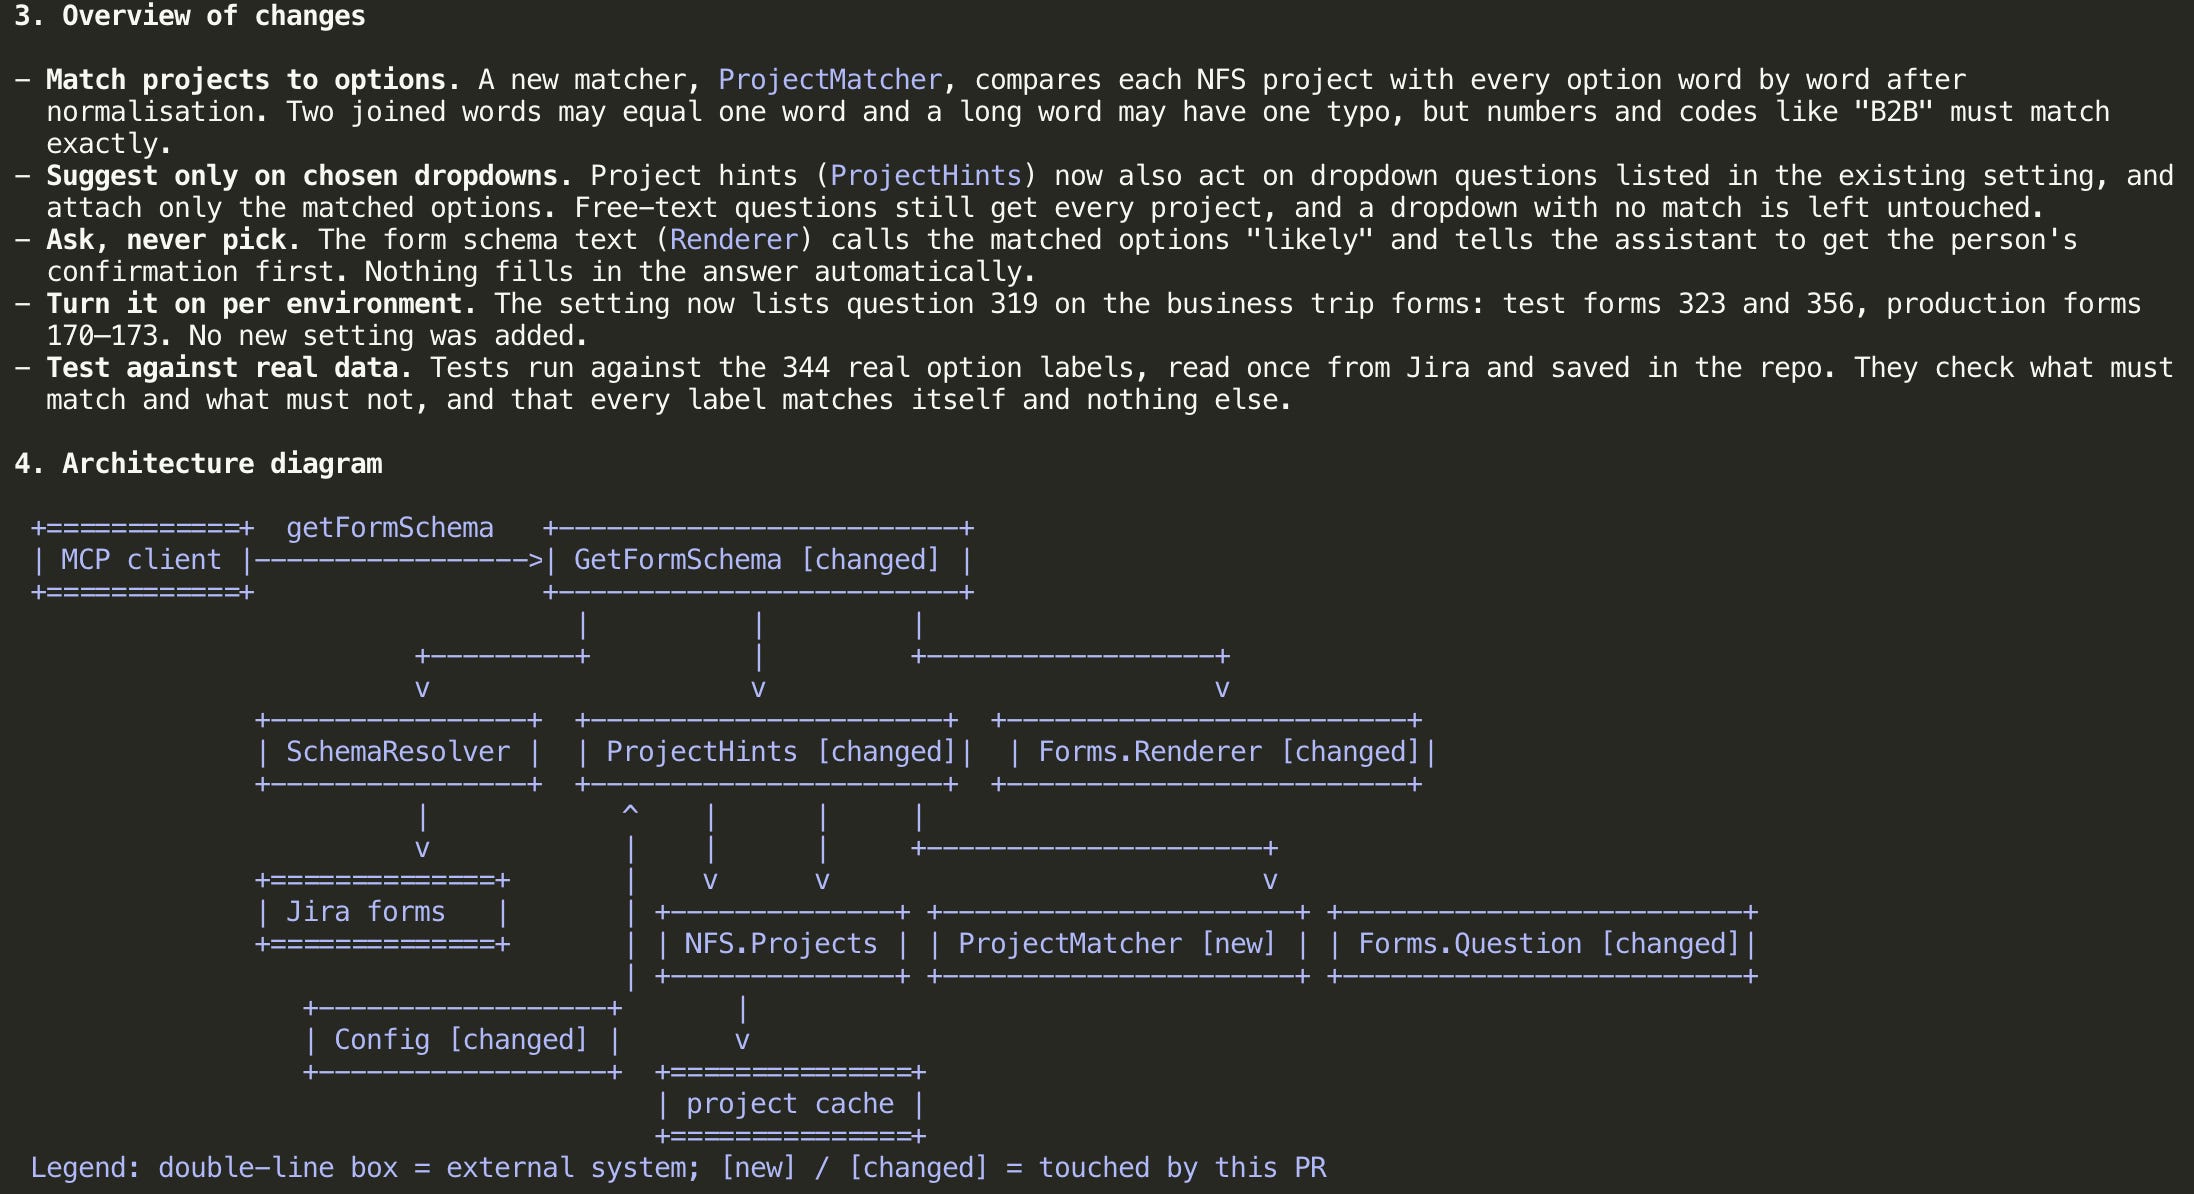
I start with the shape: which files appeared and where, what each is responsible for, which tests exist and what they protect, how access patterns changed.
A skill builds that view for me. The diff is there when I need to go deeper.
Found it? Fix it.
If I find a problem in someone else’s pull request and the intended behavior is clear, I push a fixed commit to their branch. The reviewer already has the context; handing it back makes the author pick it up again. Once you have found a problem, supplying the patch is close to free.
That leaves room for comments where a decision is still needed. If we disagree about what the code should do, we discuss it. A cheap patch doesn’t settle a disagreement about requirements.
The ceremony
Put these together and much of the comment-and-wait loop starts to look like a ceremony. The machines have already argued over the implementation, and the reviewer can fix a clear defect where they find it.
That doesn’t mean I have all the answers here. I am still wrapping my head around how this could work at scale. But I’ve experimented enough to be convinced that the old way is suboptimal by now.
Understanding still costs. When a human wrote the code, they arrived at review having worked through it. With agents, someone has to acquire that understanding afterwards.
My bet: PR-based code review in its current form goes away, and what is left is closer to signing off on shape. And the process built around it, from tickets to sprint reviews, will have to follow. And I actually think we would all be better off for it.